When OpenAI named its new GPT-5.6 models Sol, Terra, and Luna, a chunk of the internet had the same reaction: wait, aren’t those crypto coins? (Terra and Luna were, famously — a pairing that imploded back in 2022.) The jokes wrote themselves.
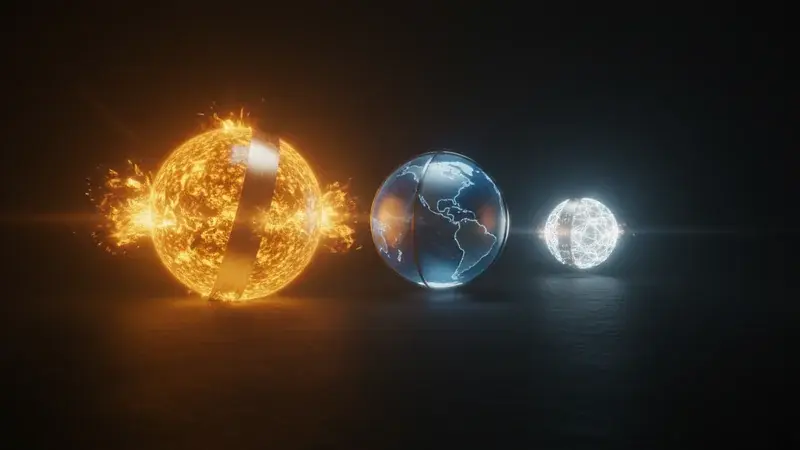
But the names aren’t a finance thing. They’re the sun, the earth, and the moon — and they’re OpenAI’s new way of telling you, at a glance, how powerful a model is. Once you get the system, it’s actually simpler than the alphabet soup of “4o, o3, 5.5” we’ve been living with. Here’s what each one is, and which you’d reach for.
Update (November 9, 2026): GPT-5.6 is no longer OpenAI’s newest family. GPT-6 Astra arrived on September 3, GPT-6 Sol and Luna on September 22, GPT-6.1 Sol on September 29 and GPT-6.1 Terra on October 26, and since October 7 GPT-6 has been rolling out as the default in ChatGPT for Plus, Pro, Business and Enterprise. GPT-5.6 isn’t retired: OpenAI says the GPT-6 rollout doesn’t retire older selectable models, GPT-5.6 Sol and Sol Pro stay selectable in ChatGPT, and Sol, Terra and Luna stay in ChatGPT Work, Codex and the API. Free and Go accounts now chat on a Luna model by default. API prices have dropped too (see below), and the plan table further down is the launch-day mapping.
Update (July 10, 2026): All three models are now live — GPT-5.6 went public in ChatGPT, Codex and the API on July 9, after a limited preview for a small group of partners that OpenAI started on June 26 at the U.S. government’s request. This guide is updated with the real plan-by-plan mapping and the final launch numbers from OpenAI’s release announcement.
The one idea that makes it click
GPT-5.6 isn’t one model. It’s a family of three, and the names are a ladder from “fast and cheap” to “slow and brilliant”:
That’s the whole mental model: Sol = sun = brightest/strongest, Luna = moon = light and quick, Terra = earth = the solid middle. The number “5.6” tells you the generation; the name tells you the tier.
And here’s the clever part for the long run: OpenAI can upgrade each tier on its own. When the cheap model gets better next time, it’s still “Luna” — you don’t have to relearn a new name. It’s “good / better / best” that’s built to last.
Sol — the heavy hitter
Sol is the one built for hard problems. OpenAI aims it at serious software engineering, scientific research, cybersecurity analysis, and long “agent” tasks where the model has to plan and work through many steps without losing the thread.
It also introduces two new “effort” settings you’ll hear about:
- “max” — lets Sol take more time to think deeply on a tough problem instead of answering fast. Useful for a knotty proof, a tricky bug, or a decision with lots of moving parts.
- “ultra” — goes a step further: it coordinates four AI agents working in parallel on your task by default (OpenAI’s charts also show 16-agent runs), each handling a separate part of the task in parallel. Think of it as Sol delegating pieces of a big job to a small team it manages itself. On OpenAI’s launch numbers, ultra lifted Sol’s score on Terminal-Bench (a hard command-line benchmark) from 88.8% to 91.9%. It runs four agents at once by default, so save it for work that genuinely deserves a team.
There’s also a Sol Pro variant — a highest-quality version that launched for Pro and Enterprise plans in regular chat (OpenAI’s help center now lists it for Business too).
For the leaderboard-watchers, the honest picture from OpenAI’s own published table: Sol tops OpenAI’s table on agent-style and command-line work (Terminal-Bench, computer-use tests), while Anthropic’s Claude models still lead elsewhere — Claude Fable 5 edges Sol on two broad intelligence indexes, and Claude’s coding specialists remain well ahead on the SWE-Bench Pro software benchmark. Nobody swept the board. For everyone else, the takeaway is simpler — Sol is the one you’d point at your most demanding work.
Terra — the everyday middle
Terra is the quiet hero. OpenAI describes it as a “balanced model for everyday work” with performance competitive with GPT-5.5, at about half the cost at launch (and cheaper since a July 30 price cut). For the vast majority of normal tasks — writing, summarizing, planning, answering questions — Terra is plenty. You’ll find it in ChatGPT Work and Codex: in regular chat, Terra isn’t an option you can pick.
It was also the free tier’s ticket in at launch: Free and Go users got Terra inside ChatGPT Work and Codex. (OpenAI’s help center now lists Terra for Free and Go in Codex.)
If Sol is the specialist you call in for the hard case, Terra is the reliable generalist for everyday work.
Luna — fast and cheap
Luna is built for speed and volume. It’s the lightest, least expensive option, meant for quick interactions and high-throughput, routine work where you’d rather have an instant answer than the deepest possible one. Short rewrites, quick lookups, simple drafts — Luna’s lane.
The launch benchmarks — and how much to trust them
OpenAI published a full comparison table at release. Here are the headline rows, kept honest by including the ones OpenAI didn’t win:
| Benchmark (what it measures) | Sol | Terra | Luna | GPT-5.5 | Best Claude |
|---|---|---|---|---|---|
| Agents’ Last Exam (long professional workflows) | 52.7% | 50.4% | 50.3% | 46.9% | 45.2% (Opus 4.8) |
| Coding Agent Index (agentic coding, independent) | 80 | 77.4 | 74.6 | 76.4 | 77.2 (Fable 5) |
| Terminal-Bench 2.1 (command-line work) | 88.8% (91.9% ultra) | 87.4% | 84.7% | 85.6% | 88% (Mythos 5) |
| OSWorld 2.0 (using a computer) | 62.6% | 50.2% | 45.6% | 47.5% | 54.8% (Opus 4.8) |
| SWE-Bench Pro (real software fixes) | 64.6% | 63.4% | 62.7% | 59.4% | 80.3% (Mythos 5) |
| GDPval-AA (expert-rated work quality) | 1,747.8 | 1,593 | 1,591.8 | 1,493.7 | 1,759.6 (Fable 5) |
| Artificial Analysis Intelligence Index | 58.9 | 55 | 51.2 | 54.8 | 59.9 (Fable 5) |
Read as a whole: Sol leads on agent-style work and computer use, Claude still leads on deep software engineering and holds a slight edge on two broad quality measures. Luna beating last generation’s flagship on three of these seven rows is the quiet story — and a Luna model is now what free ChatGPT accounts chat on by default.
There’s a second dimension the score columns hide, and OpenAI’s launch post put numbers on it using the indexes of the independent measurement firm Artificial Analysis: efficiency. By OpenAI’s figures, Sol at max reasoning took the Coding Agent Index lead while using less than half the output tokens and less than half the time of Claude Fable 5, at about a third less cost — and came within one point of Fable 5 on the broad Intelligence Index in 61% less time at roughly half the estimated cost. For anyone paying per token, near-parity quality in less than half the time, at a third to a half less cost, is arguably the real launch story — bigger than any single score gap.
Now the disclaimer, because it matters more than the table. These numbers come from OpenAI’s launch post. Vendors choose which benchmarks to publish, which competitors to include, and which settings to run — that 91.9% is Sol on ultra, a mode that runs four agents at a time, not the Sol you’ll use on a Tuesday. And benchmarks are contest conditions: clean inputs, well-defined goals, no office politics. Your actual work is ambiguous, half-documented, and full of context no leaderboard measures. A model that scores three points higher on a chart can absolutely be worse for you — because of speed, tone, how it handles your files, or how often it makes things up in your field.
One early piece of outside evidence is worth adding, because it cuts both ways. Cursor — the AI code editor — runs its own benchmark (CursorBench). On the version Cursor published at launch (CursorBench 3.2), Claude Fable 5 Max scored highest (70.5%), with GPT-5.6 Sol Max close behind (67.2%) — but Sol did it at $5.69 in model costs against Fable’s $17.32 (Cursor first showed $5.22, then corrected Sol’s cost for cache writes). So on Cursor’s benchmark at launch, Claude kept a small quality lead and Sol won decisively on price. Which of those matters more depends entirely on whether you’re paying per token. (Cursor has since moved to CursorBench 4.0, where GPT-5.6 Sol Max scores 41.7%.)
The only benchmark that settles anything is a week of your own tasks. Run the same three real jobs on Sol and on whatever you use today, and keep the one that needed less babysitting.
How this mapped to ChatGPT at launch (July 9)
Here’s the mapping OpenAI published at launch:
| Where | Free / Go | Plus | Pro / Enterprise |
|---|---|---|---|
| Regular chat | No GPT-5.6 | Sol (medium+ effort) | Sol, plus Sol Pro |
| ChatGPT Work & Codex | Terra | Sol, Terra, Luna + effort dial | Sol, Terra, Luna + effort dial |
| max setting | ✓ (togglable) | ✓ (togglable) | ✓ (togglable) |
| ultra setting | — | Codex only | ✓ in Work and Codex |
Two things worth noticing in that launch table. Free users’ only door to GPT-5.6 was the agent surfaces — ChatGPT Work and Codex — not normal chat. And Plus sat one notch below Pro twice: no Sol Pro, and no ultra inside ChatGPT Work.
Since then the map has moved: GPT-5.5 left ChatGPT, ChatGPT Work and Codex (OpenAI’s notice is dated October 14, 2026); Free and Go now chat on a Luna model by default; since October 7, GPT-6 has been rolling out as the default in paid plans’ chat, with GPT-5.6 Sol still selectable; Sol Pro is listed for Business too; and Work and Codex now offer GPT-6 models alongside the 5.6 tiers.
On timing at launch: OpenAI said the rollout would “continue gradually toward full availability over the next 24 hours.”
In regular chat, Terra and Luna aren’t options you pick: OpenAI says they live in Work and Codex. Knowing the ladder matters where you do pick: in Work and Codex, and when you choose GPT-5.6 Sol in chat. (Our guide to which ChatGPT model to use covers the picker in full.)
What this means for you
- If you’re a casual user: you mostly won’t think about this. Just know “Sol” = the powerful one if you ever get to choose — and that a free account now chats on a Luna model by default.
- If you do serious work in ChatGPT (coding, analysis, research): at launch, Sol at “max” came with every paid plan in Work and Codex — and since October 7, GPT-6 has been rolling out as the default in paid chat, so compare the two on your own hard tasks. Reserve “ultra” for the rare job that’s worth four agents.
- If you build apps or watch costs: the three tiers are a price/quality dial. At launch Sol was $5/$30, Terra $2.50/$15 and Luna $1/$6 per million tokens, with Sol priced like GPT-5.5. Since July 30 Terra is $2/$12 and Luna $0.20/$1.20; since an August 21 cut, Sol is $4/$20 on promotional pricing that OpenAI says runs until November 30, 2026. Terra at roughly half of Sol’s price is the headline; Luna is for cheap, high-volume calls. Two of OpenAI’s newer GPT-6 models list lower still: GPT-6.1 Sol at $2/$10 and GPT-6 Luna at $0.10/$0.50 (the flagship GPT-6 Astra is $10/$50). And by OpenAI’s launch figures on Artificial Analysis’s indexes, Sol finished comparable work to Claude Fable 5 in fewer tokens and less time.
- If you just want the names to stop confusing you: sun, earth, moon — brightest to lightest. That’s it.
What the tiers won’t do
- They won’t make a weak prompt smart. Pointing Sol at a vague question still gets you a vague (if eloquent) answer. Clear asks matter more than tier choice.
- They won’t all feel different for simple chat. For everyday questions, you’d struggle to tell Terra from Sol. The gap shows up on hard, multi-step work.
- They won’t be free across the board. Free and Go accounts get Terra in Codex and a Luna model in chat; Sol needs a paid plan; at launch Sol Pro and ultra-in-Work needed Pro or Enterprise (OpenAI now lists Sol Pro for Business too).
- They won’t perform like the launch chart on your desk. Benchmark scores are contest conditions at chosen settings. Judge the tiers on your own work, not the leaderboard — see the disclaimer above.
- They won’t replace knowing your field. A brighter model still doesn’t know your job. It drafts; you decide.
The bottom line
Sol, Terra, and Luna aren’t crypto coins and they aren’t a gimmick — they’re a clean “good / better / best” ladder, with the generation number (5.6) separate from the tier name. Sol for hard problems, Terra for everyday work, Luna for fast and cheap. They went live on July 9, and since September they share the stage with GPT-6: check the update at the top for where each one lives on your account now, treat the launch benchmarks as a menu rather than a verdict, and let your own work pick the winner.
Want to actually get good at picking and prompting models — the skill that outlasts every naming change? Start with ChatGPT vs Claude: Which Should You Use? or AI Fundamentals. And if the new agent side is what tempts you, our plain-English guide to ChatGPT Work is where Terra earns its keep.
Sources
- GPT-5.6: Frontier intelligence that scales with your ambition — OpenAI (July 9, 2026)
- Previewing GPT-5.6 Sol: a next-generation model — OpenAI (June 26, 2026)
- ChatGPT is now a partner for your most ambitious work — OpenAI (July 9, 2026)
- OpenAI rolls out GPT-5.6 to the public on July 9 — Engadget
- GPT-6 and other models in ChatGPT — OpenAI Help Center
- Advancing the price-performance frontier with GPT-5.6 — OpenAI (July 30, 2026)
- GPT-5.6 Sol model page — OpenAI API docs
- Model release notes — OpenAI Help Center
- CursorBench: model evals on real Cursor sessions — Cursor
- Independent model benchmarks and efficiency analysis — Artificial Analysis